Computer science concepts
Tree Algorithms, Traversal, LCA, And Dynamic Programming
These problems test mastery of tree traversal and connectivity reasoning (preorder listing, path queries, deletions) plus lowest common ancestor (LCA) and…
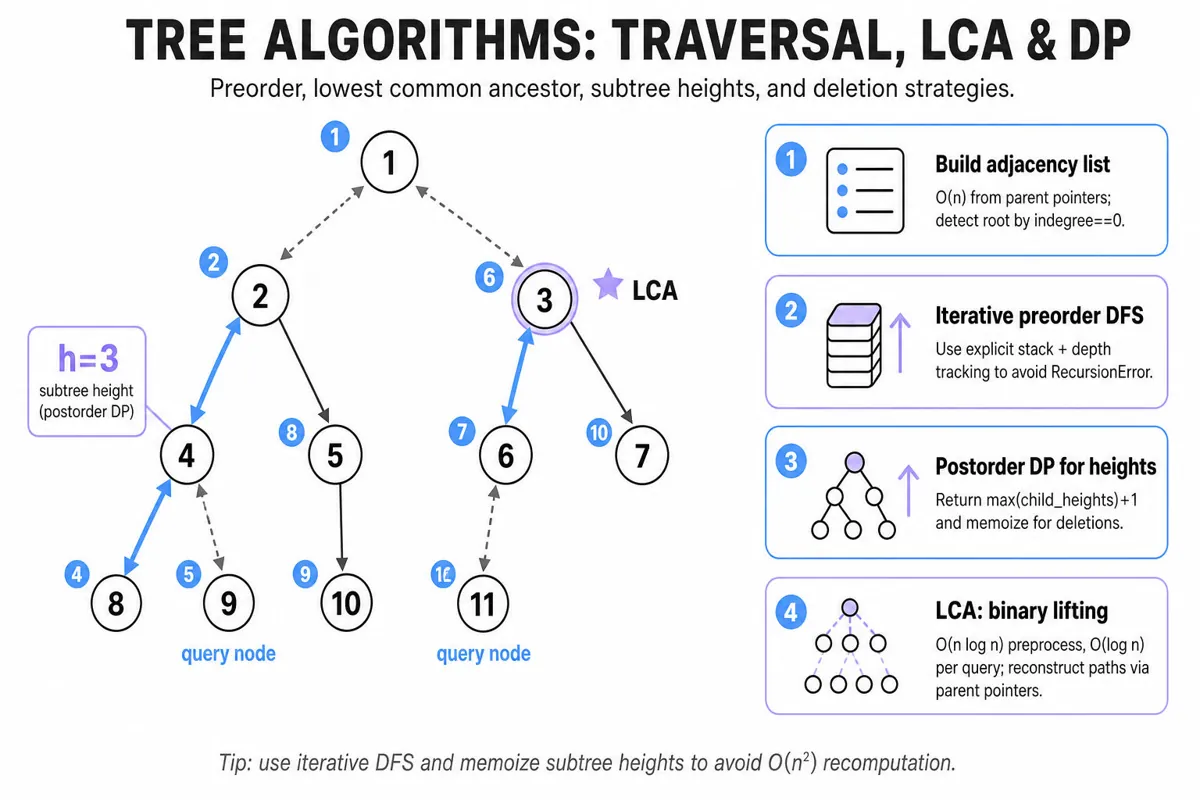
What's being tested
These problems test mastery of tree traversal and connectivity reasoning (preorder listing, path queries, deletions) plus lowest common ancestor (LCA) and search-based dynamic programming over trees. Interviewers probe ability to transform parent/child representations into usable graphs, reason about component reattachment after deletions, and produce correct, efficient traversals under edge constraints.
Patterns & templates
-
Build an
adjacency listfrom parent pointers in O(n) time; detect roots by missing parent orindegree==0. -
Use
dfs(recursive or iterative) for preorder with a runningdepthparameter to collect (id, depth) pairs in O(n) work and O(h) stack. -
Compute height with one postorder
dfsreturningmax(child_heights)+1; reuse results for deletion queries to avoid recomputation. -
For shortest-path between nodes: find LCA via parent pointers, then reconstruct paths up-to-LCA and down, O(h) time; precompute binary-lifting for repeated queries in O(n log n) preprocess.
-
For node-deletion with promotion: simulate local reconnection rules, then recompute component heights; prune search using subtree sizes and memoized heights to avoid exponential work.
-
For enumerating valid deletion sets: apply backtracking with early pruning (skip symmetric deletions), deduplicate by canonical ordering, bound by combinatorial limits.
-
Tip: prefer iterative
dfsor explicit stacks for trees deeper than ~10^4 to avoidRecursionError; track parent pointers when reconstructing paths.
Common pitfalls
Pitfall: Assuming node values are unique — many variants allow duplicate values or missing nodes; use node IDs or handle absence checks explicitly.
Pitfall: Recomputing heights from scratch per deletion without memoization leads to O(n^2) or worse; cache subtree heights and update incrementally.
Pitfall: Not addressing recursion depth or stack memory on very deep trees; always discuss iterative alternatives or tail recursion limits.
Practice these — the practice cards below cover the canonical variants — solve all of them and time yourself.