Computer science concepts
Data Pipeline Reliability And Stream Processing
These problems test practical SQL/Python data-manipulation skills: joining event and reference tables, computing per-entity metrics, and using window…
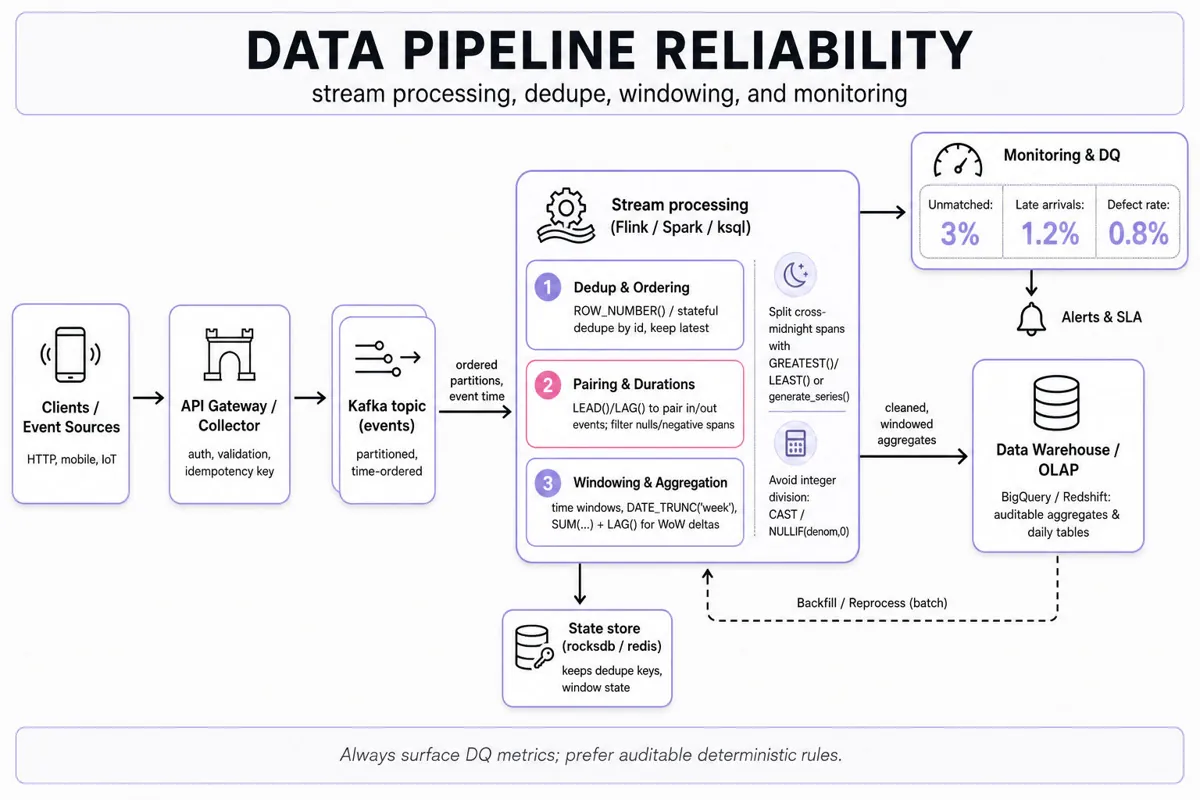
What's being tested
These problems test practical SQL/Python data-manipulation skills: joining event and reference tables, computing per-entity metrics, and using window functions to handle ordering, deduplication and week-over-week changes. Interviewers probe whether you can produce correct, auditable metrics from messy time-series data and explain tradeoffs for edge cases.
Patterns & templates
-
ROW_NUMBER()over partitions for deduping:ROW_NUMBER() OVER (PARTITION BY id ORDER BY ts DESC)to keep the latest record. -
Pair in/out events with
LEAD()/LAG()— compute durations aslead(ts)-ts, filter nulls and negative spans. -
Split cross-midnight shifts by truncating and using
GREATEST()/LEAST()orgenerate_series()for per-day allocation. -
Aggregate defects:
SUM(CASE WHEN condition THEN 1 ELSE 0 END)and defect rate =defects/NULLIF(total,0). -
Week-over-week: use
DATE_TRUNC('week', dt)thenSUM(...)+LAG()window to compute changes and percent deltas. -
Use
GROUP BY+ORDER BYwithROW_NUMBER()to extract top-N lanes/carriers per metric; tie-break on stable key (e.g.,carrier_id).
Common pitfalls
Pitfall: Pairing events by simple self-join without ordering — leads to wrong durations when multiple ins or outs exist. Always order and dedupe first.
Pitfall: Dividing by zero or using integer division — wrap denominators with
NULLIFand cast to numeric to avoid truncation.
Pitfall: Ignoring late-arriving or duplicate events — surface a data-quality metric (e.g., percent unmatched events) instead of assuming perfect data.